IT Management Antipatterns - Overview
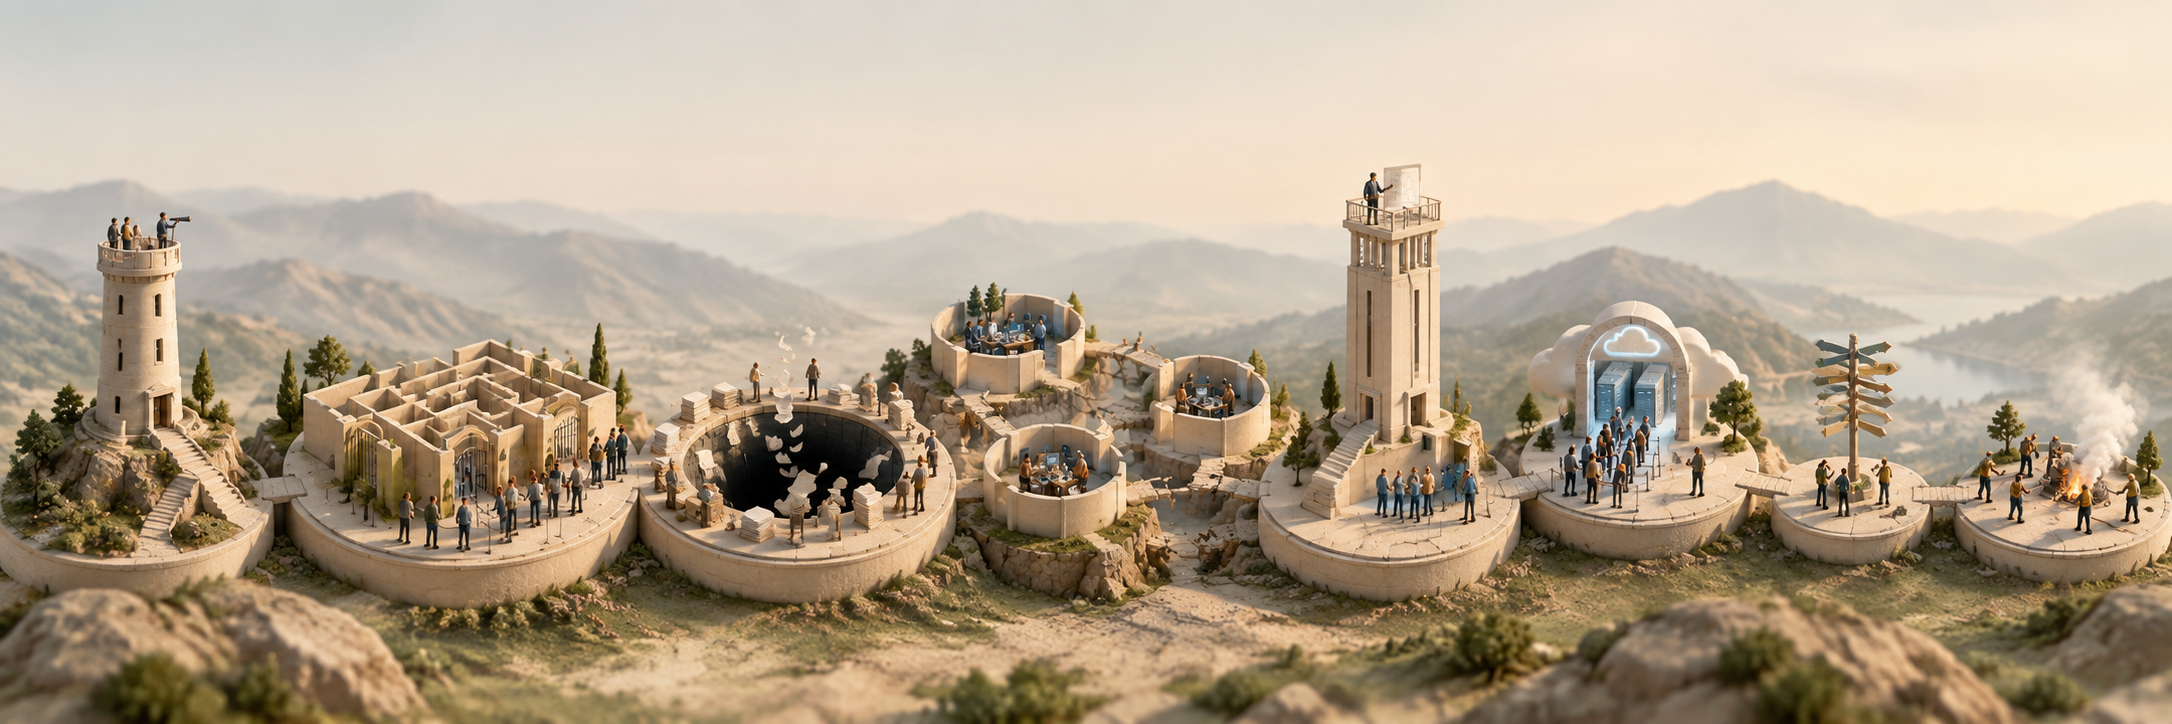
The antipatterns described in this series are recurring organizational behaviours that can undermine technology teams even when the individual people involved are competent and well intentioned. They affect leadership, decision-making, accountability, collaboration, governance, cloud adoption, and the ability of an organization to learn from its mistakes.
Some are opposites of each other: leadership can be too absent or too controlling; governance can be too weak or excessively restrictive; teams can lack ownership or defend it too aggressively. Others reinforce each other and can develop into self-sustaining organizational systems.
Articles in this series
The following summaries provide a quick way to recognize each pattern before examining its causes, consequences, and healthier alternatives in detail.
Leadership
The Invisible CTO
Senior technology leadership exists formally but is largely absent from strategic decisions, prioritization, feedback, and technological direction. Teams receive objectives but little guidance about priorities, constraints, trade-offs, or what success means. The resulting leadership vacuum forces lower levels of the organization to invent their own interpretations of strategy, often producing substantial technical activity without coherent technological direction.
In short: leadership responsibility exists, but leadership direction does not.
The Puppet Master
A manager delegates work but retains control over the decisions required to perform it. Specialists need approval for routine choices, technical decisions are repeatedly overridden, and teams gradually optimize for predicting the manager's preferences rather than exercising professional judgement. The manager eventually becomes a human single point of failure.
In short: tasks are delegated, but decision-making authority is not.
The Omniscient Manager
Managerial authority is treated as if it automatically implied technical expertise. Specialists are consulted but their judgement is routinely overridden in domains where the manager has less knowledge or direct experience. Expertise becomes advisory while hierarchy determines technical truth.
In short: organizational authority is confused with subject-matter expertise.
The Late Oracle
Management provides little meaningful guidance while work is being designed and implemented but becomes highly opinionated once the result is nearly complete. Feedback that could have influenced the outcome arrives only after important decisions have become expensive to reverse, converting guidance into criticism and creating avoidable rework.
In short: feedback arrives when it is too late to improve the work efficiently, turning guidance into criticism and avoidable rework.
Decision Making
The Black Hole
Proposals, risks, requests for decisions, escalations, and technical concerns travel upward through the organization, but no clear decision comes back. Issues remain indefinitely unresolved, forcing teams either to wait or to proceed without authority. Eventually people learn that raising an issue creates effort without producing an outcome and stop escalating problems altogether.
In short: information flows upward, but decisions and feedback do not flow back down.
The Mission Impossible
People are held accountable for delivering outcomes whose requirements, constraints, priorities, or acceptance criteria were never clearly communicated. Guidance is limited during execution, yet the finished work may be rejected according to expectations that become apparent only afterwards. The team is effectively expected to hit a target it cannot see.
In short: expectations are vague before the work but precise when the work is judged.
The Moving Target
Requirements, priorities, or objectives repeatedly change while the original deadlines, resources, and expectations remain unchanged. Change itself is not the problem; the antipattern appears when the organization behaves as though changing scope has no consequences for schedule, capacity, cost, quality, or risk.
In short: the organization moves the target but still evaluates the team against the original shot.
Read the Decision Making article
Accountability
The Responsibility Trap
People are held accountable for outcomes without receiving the authority, resources, information, or control necessary to influence them. Responsibility flows downward while important decisions remain elsewhere, allowing the organization to assign accountability independently from the power required to exercise it.
In short: accountability is assigned without the authority needed to fulfil it.
The Accountability Inversion
The organization becomes more willing to challenge the people reporting persistent poor performance than the people responsible for it. Reliable employees compensate for missed work, responsibilities are quietly redistributed, and legitimate concerns are reframed as communication or interpersonal problems. Support and empathy become distorted into avoidance of difficult but necessary performance management.
In short: the person exposing the accountability problem becomes easier to challenge than the accountability problem itself.
The Messenger Shooter
Persistent problems are tolerated more readily than the people who repeatedly expose them. Employees who raise uncomfortable evidence about poor performance, technical risks, management failures, or organizational dysfunction are characterized as negative, difficult, or uncooperative. The organization gradually teaches people that reporting a problem can be more dangerous than allowing it to continue.
In short: the problem is tolerated; reporting the problem is punished.
Read the Accountability article
Organization
The Ivory Tower
Architects, governance specialists, or other central technical authorities define standards and architectures while remaining insufficiently connected to the teams that must implement and operate them. Architecture becomes a one-way flow of instructions rather than a continuous exchange between strategy, implementation, operations, and real-world feedback.
In short: architecture is designed at a distance from the reality that must implement it.
The Silo Kingdoms
Specialized teams gradually become organizational territories that protect their technologies, responsibilities, information, and decision authority. Networking, security, operations, development, databases, and cloud teams may each optimize their own domain while end-to-end delivery suffers from hand-offs, queues, conflicting priorities, and weak shared ownership.
In short: every kingdom can succeed while the organization fails.
Cloud Governance
The Permission Maze
Routine work requires navigating excessive, overlapping, unclear, or historically accumulated approvals. Each control may once have had a legitimate purpose, but together they create an organizational maze in which obtaining permission can require more effort than performing the work itself.
In short: the organization controls routine work primarily through friction rather than effective guardrails.
The Governance Theatre
The visible activities of governance become more important than the outcomes governance was created to achieve. Policies, committees, architecture reviews, risk registers, approvals, compliance dashboards, and documentation proliferate while risks remain unresolved, controls are inconsistently enforced, and exceptions become permanent.
In short: the organization accumulates evidence that governance is happening without equivalent evidence that risks are actually under control.
The Cloud Gatekeeper
A central cloud or platform team created to enable safe cloud adoption gradually becomes the mandatory intermediary for cloud activity. Accounts, infrastructure, IAM, networking, architecture, and new services require its intervention. As cloud adoption grows, dependency on the central team grows with it, turning scarce cloud specialists into a manual workflow engine.
In short: the team created to enable cloud adoption becomes the team everyone must pass through to use the cloud.
The Datacenter in the Sky
Infrastructure has moved to the public cloud, but the organization continues operating it according to traditional datacenter assumptions: static capacity, manual provisioning, server-centric thinking, ticket-driven operations, long-lived infrastructure, weak automation, and centralized control. The technology has changed while the operating model has not.
In short: the datacenter moved; the organization did not.
Read the Cloud Governance article
Operations
The Firefighter Factory
The organization becomes highly effective at responding to emergencies but consistently fails to eliminate the conditions that create them. Heroic recovery is visible and rewarded while preventive engineering, automation, resilience, maintenance, and technical-debt reduction are repeatedly postponed. The same categories of incidents therefore return.
In short: the organization becomes excellent at putting out fires while continuing to manufacture them.
The Blame Machine
Failures trigger a search for the individual responsible rather than an investigation into the technical, organizational, procedural, and management conditions that made the failure possible. Identifying who made the final mistake becomes a substitute for understanding why one person's mistake was sufficient to make the system fail.
In short: finding someone to blame replaces learning how the system failed.
References
Core bibliography
Forsgren, Nicole; Humble, Jez; Kim, Gene. Accelerate: The Science of Lean Software and DevOps: Building and Scaling High Performing Technology Organizations . IT Revolution, 2018.
Based on four years of research into software-delivery performance and the organizational and technical capabilities associated with it. Particularly relevant to leadership, culture, deployment practices, autonomy, continuous delivery and organizational performance.
Kim, Gene; Humble, Jez; Debois, Patrick; Willis, John; Forsgren, Nicole. The DevOps Handbook , 2nd ed. IT Revolution, 2021.
Useful for flow, feedback loops, organizational boundaries, automation, security integration, deployment practices and continuous improvement.
Skelton, Matthew; Pais, Manuel. Team Topologies: Organizing Business and Technology Teams for Fast Flow . IT Revolution, 2019; 2nd ed. 2025.
One of the strongest references for Silo Kingdoms, Ivory Tower, Cloud Gatekeeper and Permission Maze . Its model of stream-aligned, platform, enabling and complicated-subsystem teams is particularly useful for explaining why centralized specialist teams should often enable other teams rather than become permanent dependencies.
Beyer, Betsy; Jones, Chris; Petoff, Jennifer; Murphy, Niall Richard, eds. Site Reliability Engineering: How Google Runs Production Systems . O'Reilly, 2016.
Beyer, Betsy; Murphy, Niall Richard; Rensin, David K.; Kawahara, Kent, eds. The Site Reliability Workbook . O'Reilly, 2018.
These are particularly valuable for Firefighter Factory, Blame Machine, Governance Theatre and the general distinction between repetitive operational work and engineering improvement. Google's SRE material explicitly treats repetitive operational work as toil and recommends measuring and systematically eliminating it.
Westrum, Ron. “A Typology of Organisational Cultures.” Quality and Safety in Health Care 13(Suppl II), 2004, pp. ii22–ii27.
Westrum focuses heavily on information flow and how organizations respond when warning signs and bad news emerge. This provides a strong theoretical basis for the Black Hole, Blame Machine, Invisible CTO and Silo Kingdoms.
Westrum — full article via PubMed Central
Dekker, Sidney. The Field Guide to Understanding 'Human Error' , 3rd ed. Ashgate, 2014.
Excellent foundation for Blame Machine and Firefighter Factory . Dekker challenges the “bad apple” interpretation of failure—the assumption that a basically safe system fails because an unreliable individual made a mistake—and instead examines the system conditions surrounding human error.
The Field Guide to Understanding Human Error
Online references
AWS — Executive Sponsorship / Operational Excellence
AWS — Program Governance and Decision Rights
AWS — Cloud Operations and Platform Enablement
AWS — CAF Security: Guardrails, Not Gates
Microsoft — Silos and Fiefdoms
Microsoft — Cloud Readiness Antipatterns
DORA — Transformational Leadership
Google SRE — Eliminating Toil
Google SRE — Postmortem Culture: Learning from Failure
Google Cloud — Continuous Improvement and Innovation