IT Management Antipatterns - Cloud Governance
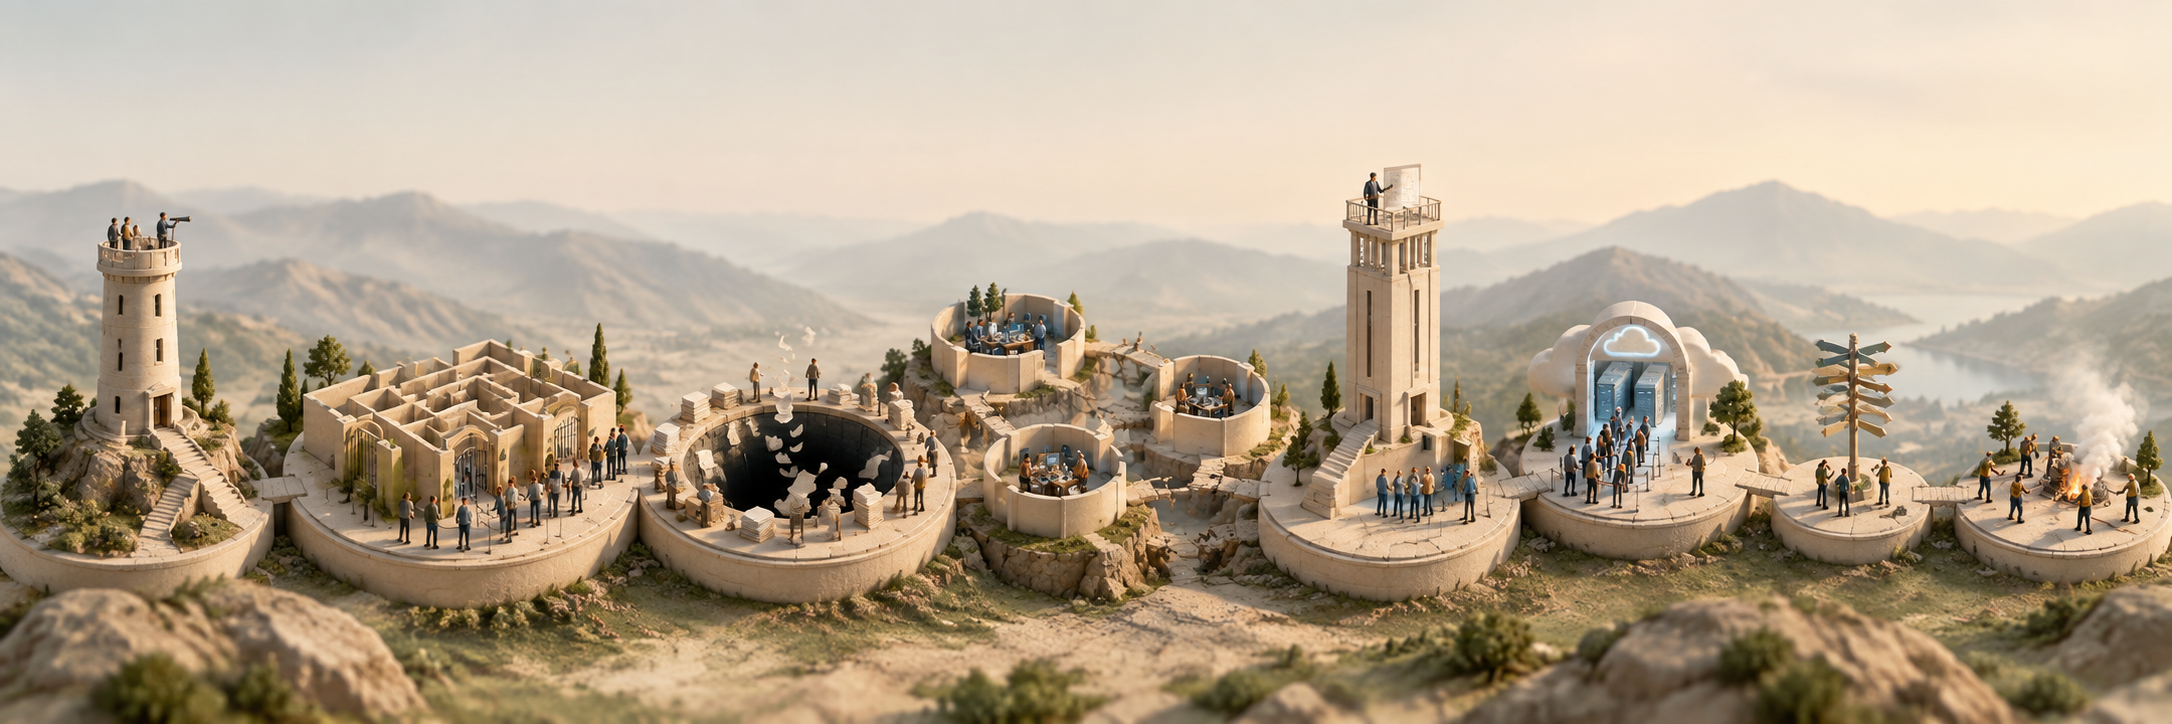
Cloud governance becomes counterproductive when control creates unnecessary friction or when cloud environments are managed using traditional datacenter practices. This section explores antipatterns that limit autonomy, slow down delivery, and prevent organizations from taking full advantage of cloud capabilities.
Articles in this series
The Permission Maze
The Permission Maze is the organizational antipattern in which getting work done requires navigating an excessive, unclear, or overlapping network of approvals, reviews, committees, tickets, and authorization processes. Each individual control may have been introduced for a legitimate reason: security, compliance, cost control, architecture consistency, operational stability, or risk management. Over time, however, additional controls accumulate while obsolete ones are rarely removed. Different departments create their own approval processes, often without considering those already imposed by other teams. The result is a maze.
Engineers know where they want to go, but reaching the destination requires finding a path through Security, Architecture, Networking, Operations, Compliance, Finance, Change Management, and several layers of management. The organization eventually spends more effort obtaining permission to do the work than performing the work itself.
How to recognize it
Typical symptoms include:
- Engineers need several approvals before making relatively routine changes.
- Nobody can clearly explain the complete approval process from beginning to end.
- Different teams provide conflicting instructions about which approvals are required.
- Approval requirements are discovered progressively rather than documented in advance.
- A request approved by one group can subsequently be rejected by another.
- Multiple approval steps evaluate essentially the same risk.
- Engineers regularly ask, "Who needs to approve this?"
- Requests remain in queues because the responsible approver is unavailable.
- Approval boards meet only at fixed intervals, making their calendar part of the project's critical path.
- Routine technical changes require management approval from people with little knowledge of the implementation.
- Different applications of the same type go through substantially different processes depending on who is involved.
- Teams maintain informal knowledge about which person can "get something through."
- Engineers spend substantial time creating presentations, tickets, forms, and documents primarily to satisfy approval processes.
- Emergency procedures are frequently used simply because the normal process is too slow.
- Experienced employees know unofficial shortcuts that new employees do not.
- Nobody periodically reviews whether existing approval steps are still necessary.
Negative effects on the organization
The Permission Maze is rarely deliberately designed. It normally grows incrementally. An incident occurs, so an additional approval is introduced. A security problem occurs, so Security adds a review. Costs increase, so Finance adds another control. The problem is that organizations are usually much better at adding controls than removing them. Years later, the original circumstances may no longer exist, technology may have changed, automated controls may have replaced manual ones, and the people who introduced the process may have left. The approval remains.
The most immediate consequence is increased lead time. A technical change requiring two hours of engineering work may take three weeks to deliver because it spends most of its lifecycle waiting in approval queues. From the organization's perspective, the change appears to have taken three weeks. Organizations often attempt to improve delivery speed by making engineering teams more productive while ignoring the much larger amount of time consumed by organizational queues.
The Permission Maze therefore creates an important paradox: the organization tries to reduce risk by adding controls, but eventually makes safe changes so expensive that people become reluctant to make them. Processes intended to reduce risk can therefore begin to create risk themselves.
Approval time is not simply empty calendar time. While waiting, engineers must manage unfinished work. They switch to other activities, then return days or weeks later and reconstruct the original context. The engineer may need to reread documentation, messages, and code simply to remember why the change was required. A two-hour activity can therefore consume considerably more than two hours of engineering capacity even if the approval itself requires no work from the engineer. Multiply this effect across hundreds or thousands of changes and the organizational cost becomes significant.
Negative effects on people
The Permission Maze teaches employees that initiative creates administrative work. The engineer makes a perfectly rational decision: "It's not worth it." The improvement never happens. Over time, this can create a culture in which employees stop proposing small improvements because the transaction cost exceeds the perceived benefit. This is particularly damaging to continuous improvement, where organizational progress often consists of hundreds of relatively small changes rather than a few large projects.
Another unhealthy consequence is that navigating the organization becomes a specialized skill. These employees become effective partly because they understand the bureaucracy rather than because they are better at solving technical problems. New employees, consultants, and people outside established networks are disadvantaged because they do not possess this informal knowledge. The organization has effectively created an undocumented API for itself. And, like any undocumented API, people discover how it works through trial and error.
The Permission Maze is particularly damaging in cloud environments because one of the fundamental advantages of cloud computing is on-demand access to programmable infrastructure. If creating an AWS account, deploying infrastructure, obtaining network connectivity, assigning permissions, or provisioning a development environment requires several weeks of tickets and manual approvals, the organization has recreated many of the limitations of traditional infrastructure on top of a cloud platform.
Microsoft's Cloud Adoption Framework warns against centralized cloud functions becoming bottlenecks and recommends balancing governance with team empowerment. Its guidance on cloud operating models emphasizes enabling workload teams while maintaining appropriate platform and governance responsibilities.
Another cause of the Permission Maze is treating every change as if it carried the same level of risk. Creating a temporary development resource is not equivalent to changing a production identity policy. Governance should therefore be risk-based. Low-risk, reversible, well-understood changes should require little or no manual approval. Higher-risk, irreversible, unusual, expensive, or compliance-sensitive decisions may legitimately require additional review.
The healthy pattern: Guardrails, Not Gates
The first step is surprisingly simple: map the maze. Take a representative change—for example, creating a new cloud workload—and document every step required from initial request to production. This exercise often reveals that much of the delivery time consists not of work but of queues. Require every approval process to have a reason for existing.
Organizations frequently use manual approval because it provides a visible indication that somebody has reviewed an action. But an approval does not necessarily guarantee that the action is safe. An approver can misunderstand the request. Automated controls can often provide stronger and more consistent protection.
The exact mechanisms depend on the environment, but the principle remains the same: where a rule can be expressed and reliably enforced automatically, manual permission should not necessarily be the primary control.
This leads to one of the most important principles of modern cloud governance: prefer guardrails to gates.
Instead of approving every infrastructure deployment, teams can deploy through standardized pipelines that automatically enforce policies. Instead of requiring a security review for every ordinary architectural decision, security teams can define approved patterns that workload teams may use independently.
Human review can then concentrate on exceptions and genuinely high-risk decisions. This changes governance from an organization that blocks work into an organization that establishes the conditions under which work can safely proceed.
The principle is:
Make the safe path the easy path.
If engineers can perform the correct action quickly, independently, and consistently, governance becomes an enabler rather than an obstacle. A mature organization should not measure the strength of its governance by the number of people required to approve a change. It should measure it by how reliably people can make changes without exceeding the organization's acceptable boundaries.
The Cloud Gatekeeper
The Cloud Gatekeeper is the organizational antipattern in which a central cloud, platform, architecture, or governance team becomes the mandatory intermediary for most cloud decisions and activities.
The team was usually created for good reasons. Cloud adoption introduces unfamiliar technology. Security needs to be maintained. Accounts need governance. Costs need control. Identity needs standardization. The organization therefore creates a Cloud Center of Excellence, Cloud Platform Team, Cloud Governance Team, or similar central function. Initially, the team provides expertise and establishes the foundations required for safe cloud adoption. But gradually its role changes.
Instead of enabling other teams to operate safely in the cloud, it becomes the organization that allows other teams to use the cloud. Eventually the organization has moved from "How can we enable teams to use AWS safely?" to "How can we prevent teams from using AWS without us?". The cloud team has become the Cloud Gatekeeper.
How to recognize it
Typical symptoms include:
- Almost every cloud-related activity requires approval from a central team.
- Application teams cannot create or configure common infrastructure independently.
- AWS accounts require lengthy manual provisioning processes.
- Engineers need tickets for routine IAM, networking, DNS, logging, or infrastructure changes.
- A central team manually performs activities that could be automated.
- New AWS services require lengthy certification before teams may use them.
- The list of approved services evolves much more slowly than AWS itself.
- Platform engineers become involved in nearly every project.
- Cloud architects spend significant time reviewing routine designs.
- Application teams cannot deploy without waiting for another team's backlog.
- The cloud team owns Terraform modules but application teams cannot easily contribute to them.
- Standards exist primarily as restrictions rather than reusable solutions.
- Exceptions require senior approval even when the associated risk is small.
- Engineers design solutions around what the cloud team will approve rather than what best solves the problem.
- Teams create unofficial workarounds to avoid central processes.
- Central cloud engineers complain that application teams constantly need support.
- Application teams complain that the cloud team is blocking delivery.
- The cloud team's backlog grows continuously as cloud adoption increases.
Negative effects on the organization
The Cloud Gatekeeper often begins as a successful team. Its members are usually among the organization's most experienced cloud engineers. They understand the cloud. Because they know how to solve difficult cloud problems, projects naturally depend on them. Initially this works extremely well. Five application teams ask ten cloud experts for assistance. Then twenty application teams arrive. Then one hundred. The central team's expertise has not scaled at the same rate. The very competence that made the team valuable has transformed it into a bottleneck. This produces an important organizational paradox: the more successful cloud adoption becomes, the less scalable a gatekeeper model becomes.
A central team can scale its expertise in two fundamentally different ways. It can perform work for other teams. Or it can encode its expertise so that other teams can perform the work safely themselves. The first model scales approximately with the number of people in the central team. The second can scale across the organization.
Consider account provisioning. A gatekeeper model might require:
Request → Review → Security approval → Network approval → Cloud team configuration → Validation → Handover
A platform model might provide:
Request → Automated account vending → Organizational policies → Network integration → Logging → Security baseline → Ready
The governance requirements may be almost identical. The difference is that in the second model the organization's knowledge has been encoded into the platform. The central team no longer needs to personally participate in every transaction.
Governance does not necessarily require human intervention. An organization may require that only approved AWS Regions are used. A traditional operating model may enforce these requirements through reviews and approvals. Cloud platforms allow many of them to be enforced or continuously evaluated through technology, like Service Control Policies.
AWS's security guidance explicitly describes the principle as "Guardrails, not gates": minimize friction, avoid centralized blocking manual workflows when safe alternatives exist, strive for self-service, and encode security requirements into the toolchain.
The distinction is fundamental:
- A gate requires permission before proceeding.
- A guardrail allows movement while preventing unacceptable outcomes.
One of the promises of cloud computing is rapid access to infrastructure. An engineer can technically provision compute capacity in seconds. An environment can be reproduced from code. But organizational processes can neutralize this advantage if creating an AWS account requires three weeks and network connectivity requires another two.
Security is frequently used to justify centralized cloud control, sometimes correctly. Changes to organization-wide Service Control Policies, identity federation, central networking, security logging, encryption foundations, or other high-impact controls may reasonably require specialized review and limited privileges. But not every AWS decision carries equivalent risk. Creating an S3 bucket inside an established security boundary is not equivalent to modifying organization-wide IAM controls. If every action requires the same governance mechanism, the organization is not applying security according to risk. It is applying centralization according to convenience.
AWS's governance guidance explicitly recommends scalable guardrails with minimal impact on agility, while its platform guidance describes packaged, reusable cloud products and automated provisioning as mechanisms for combining governance with faster delivery.
Large organizations sometimes maintain lists of AWS services that teams are permitted to use. There can be legitimate reasons for this. The problem appears when approval cannot keep pace with the platform. AWS evolves continuously. New services appear, existing services gain capabilities. If the certification process takes months, application teams naturally continue using older approved technologies. The organization may therefore spend significant money migrating to cloud while systematically preventing itself from using many of the capabilities that justified the migration. The approval process intended to reduce technology risk begins creating technology stagnation risk. A mature governance model should therefore distinguish between services that genuinely require deep review and those that can be admitted through standardized risk categories and automated controls.
Infrastructure as Code can also become part of the antipattern. A central cloud team may correctly decide that infrastructure should be provisioned through Terraform. It creates modules. It establishes repositories. But eventually every change to cloud infrastructure must be implemented or approved by that team. Infrastructure as Code has been introduced technically while the organizational workflow remains ticket-driven. This misses much of the value of IaC. A stronger model allows workload teams to consume standardized Terraform modules and pipelines themselves within defined boundaries. The central team owns the platform capability. It does not need to own every resource created through it.
The longer the Gatekeeper model exists, the harder it becomes to escape. Application teams do not develop cloud expertise because they are not permitted to make meaningful cloud decisions. Because they lack expertise, the central team concludes that they cannot safely be trusted with cloud decisions. More decisions are centralized and the application teams learn even less.
The cycle becomes:
Centralize decisions → Teams gain less experience → Teams remain dependent → Centralization appears justified → Centralize more decisions
This is an organizational dependency loop.
Excessive control does not necessarily eliminate risky behaviour. It can displace it. If the official route for obtaining infrastructure is sufficiently slow, engineers and business units begin looking for alternatives. Experiments occur outside corporate controls. The organization may believe it has strengthened governance by tightly controlling the official cloud environment. In reality, it may have pushed activity into environments where it has less visibility and less control. The safest path therefore needs to be not only secure but practical. If bypassing governance is dramatically easier than following governance, the governance model is unstable.
Over time, the central cloud organization can develop its own identity. It owns the AWS platform, it has specialized knowledge, it controls privileged access. Its position becomes increasingly important because every cloud initiative depends on it. At this point, the Cloud Gatekeeper overlaps with the Silo Kingdoms antipattern.
Negative effects on people
Gatekeeping is frustrating for application teams, but it is also damaging to the gatekeepers themselves. Highly skilled cloud engineers can spend much of their time approving routine requests, creating accounts, reviewing repetitive architectures, and attending governance meetings. The organization has hired scarce specialists and converted them into a manual workflow engine. This contributes directly to the Firefighter Factory and Permission Maze. The cloud team becomes overloaded. The organization needs to reduce the number of transactions that require cloud engineers.
The Healthy Pattern: The Cloud Enabler
As with other antipatterns, the solution should not be taken to the opposite extreme. Cloud democratization does not mean unrestricted cloud access, some decisions have broad consequences. The objective is therefore not: "Everyone can do everything." It is: "Teams can independently perform routine activities within clearly defined boundaries, while exceptional or high-risk decisions receive appropriate oversight."
The healthy alternative is a cloud organization whose primary objective is not to control cloud consumption manually but to make safe cloud consumption easy. Instead of manually operating capabilities on behalf of every team, it packages them into reusable services.
AWS describes platform engineering in similar terms: compliant multi-account environments, reusable cloud products, automated provisioning, Infrastructure as Code, and self-service consumption of approved capabilities. AWS's Operational Excellence guidance goes further: its Cloud Operations and Platform Enablement model describes platform teams codifying reference architectures and providing them through self-service mechanisms, with application teams progressively taking ownership as their capabilities mature.
The principle is:
The purpose of cloud governance is not to put a cloud expert in the path of every decision. It is to embed cloud expertise into the platform so that good decisions can be made safely without one.
The Governance Theatre
Governance Theatre is the organizational antipattern in which the visible mechanisms of governance become more important than the outcomes they are supposed to produce.
The organization has policies. It has review boards. It has approval workflows. It has risk registers. Every important decision appears to pass through an impressive governance structure. Yet serious risks remain unresolved, standards are inconsistently enforced, exceptions become permanent, controls are manually bypassed, ownership is unclear, and known problems persist for years.
The organization is performing the activities of governance without consistently achieving the purpose of governance . Governance has become theatre.
How to recognize it
Typical symptoms include:
- Success is measured by completion of governance activities rather than by reduction of risk.
- Teams must produce extensive documentation that few people subsequently use.
- Architecture reviews focus heavily on templates and required fields rather than important architectural risks.
- Approval boards routinely approve requests with limited meaningful discussion.
- The same risks appear in reports quarter after quarter without remediation.
- Policies define requirements that are not technically enforced.
- Exceptions remain open indefinitely.
- Controls exist primarily to satisfy audit requirements.
- Employees know which mandatory processes can safely be ignored.
- Documentation is created immediately before an audit and receives little attention afterward.
- Compliance dashboards remain green despite significant known operational problems.
- Management receives metrics showing process compliance but little information about whether the underlying systems are actually safe, reliable, or well governed.
- The same information is manually copied between tickets, spreadsheets, presentations, and governance systems.
- Reviews happen after important decisions have effectively already been made.
- Governance meetings produce minutes but few consequential decisions.
- Policies accumulate while obsolete policies are rarely removed.
- Nobody can clearly explain which specific risk a particular control is intended to mitigate.
- Teams optimize for passing the review rather than improving the system.
Negative effects on the organization
The problem is not governance itself. Technology organizations need governance. Responsibilities and decision rights need to be clear. Governance Theatre appears when answering these questions becomes secondary to demonstrating that a governance process exists. A common mistake is assuming that performing a governance activity means that the associated risk is controlled.
Consider a mandatory architecture review. A team produces a document. Several people attend a meeting. The board approves it. But what does that actually tell us? It does not necessarily tell us whether the architecture is secure. It does not tell us whether resilience requirements are implemented. It does not tell us whether the assumptions presented during the meeting remain true six months later. It does not tell us whether the approved architecture resembles what was eventually deployed. The organization has evidence that a meeting occurred. It does not necessarily have evidence that a risk was controlled.
Documentation is important. Architecture decisions, risk acceptance, operational procedures, security requirements, ownership, and important technical assumptions should often be documented. But documentation becomes theatrical when its primary purpose is proving that documentation exists.
Governance Theatre often produces reassuring dashboards. The numbers look excellent. Then a serious incident occurs. Management is surprised. The problem may be that the organization was measuring compliance with the governance process rather than effectiveness of the governance system.
This distinction becomes especially important in regulated environments. An organization may successfully demonstrate that a control exists while still having significant residual risk. Conversely, a technically strong security mechanism may not satisfy a regulatory requirement if the organization cannot demonstrate or document it appropriately. Compliance and security overlap, but they are not identical.
Passing an audit does not prove that every system is secure. Completing a risk assessment does not remove the risk. Approving an architecture does not make the architecture reliable. Signing a change request does not make the change safe. Governance should therefore distinguish between evidence that a process was followed and evidence that the intended outcome was achieved. Governance Theatre and the Permission Maze frequently reinforce each other.
A particularly common cloud example is governance based almost entirely on written policy. The organization states:
- All storage must be encrypted.
- Public access is prohibited.
- Resources must contain mandatory tags.
- Logging must be enabled.
- Only approved regions may be used.
- Privileged access must be controlled.
- Backups must meet defined requirements.
These may all be sensible policies. But if compliance depends entirely on engineers remembering and manually implementing them, the organization has created expectations rather than strong controls.
Cloud platforms provide opportunities to move governance closer to the technology itself. Depending on the requirement, controls can be implemented or supported through organizational policies, IAM controls, Infrastructure as Code, CI/CD checks, configuration monitoring, automated remediation, security services, standardized platform components, and continuous compliance evaluation.
AWS's governance guidance emphasizes establishing mechanisms that enable teams to operate within defined organizational priorities and responsibilities rather than relying solely on documentation or manual oversight.
The principle is straightforward: if an important rule can be reliably enforced automatically, enforcement is generally stronger than repeatedly asking people to remember it.
Risk registers are another common source of Governance Theatre. Identifying and recording risk is valuable. But a risk register becomes theatrical when recording the risk is treated as the final action. A serious risk is identified. Months pass. Nothing changes. Eventually the continued existence of the risk becomes normal. The organization has transformed a technical or business problem into an administrative object.
Official policies describe the intended governance model. Exceptions often reveal the real one. Suppose policy requires every workload to follow a particular security standard, but exceptions are routinely granted because the standard is difficult to implement. Over time, dozens of applications operate outside the standard. An exception process without expiration, ownership, and review can gradually replace the policy it was intended to complement.
Organizational processes tend to develop constituencies. A committee exists and people are assigned to it. Roles are created around maintaining the process. Eventually questioning whether the process still creates value becomes organizationally difficult; the process begins justifying its own existence. This is why governance mechanisms need periodic review just like technical systems. A control that was appropriate five years ago may now be redundant, ineffective, or actively harmful. Good governance therefore governs itself.
Negative effects on people
Governance Theatre gradually teaches engineers to treat governance as an obstacle rather than as a mechanism for improving decisions. People learn which words reviewers expect. Documents are written to obtain approval rather than communicate useful information. Risk assessments become exercises in selecting acceptable values. Architecture diagrams are simplified to avoid unnecessary questions. Teams disclose the minimum information necessary to progress. This is dangerous because Governance depends on accurate information. When the governance process becomes sufficiently burdensome or performative, it creates incentives for employees to provide less information to governance.
The Healthy Pattern: Outcome-Based Governance
The healthy alternative is not less governance by default. It is governance proportional to risk and connected to measurable outcomes.
Every significant governance mechanism should be able to answer:
- What risk are we controlling?
- What outcome do we expect?
- How do we know the control is working?
- Can the control be automated?
- What evidence demonstrates effectiveness?
- Who owns the residual risk?
- When will this control be reviewed again?
Governance processes should be simplified where they provide little value and strengthened where important risks remain insufficiently controlled. Where possible, policies should become executable controls. Security requirements should become automated checks. Approved infrastructure patterns should become reusable modules and platform services. Configuration requirements should be continuously evaluated. Low-risk, reversible decisions should be delegated.
Human governance should concentrate on areas where judgement genuinely adds value: significant exceptions, material risk acceptance, major architectural trade-offs, regulatory interpretation, strategic technology decisions, and irreversible commitments.
The principle is:
Do not measure governance by how many controls you have. Measure it by whether the risks those controls were created to manage are actually under control.
The Datacenter in the Sky
Datacenter in the Sky is the cloud management antipattern in which an organization migrates infrastructure to a public cloud but continues to design, operate, govern, and manage it essentially as if it were still running in a traditional datacenter.
Infrastructure is manually provisioned. Servers are treated as permanent assets. Capacity is allocated in advance. Changes require tickets. Environments are manually configured. Automation remains limited. Teams continue organizing responsibilities around infrastructure components rather than services and applications.
The organization has adopted cloud technology without adopting a cloud operating model.
How to recognize it
Typical symptoms include:
- Most workloads run on virtual machines even when managed or serverless alternatives would be appropriate.
- Cloud resources are treated as long-lived servers rather than replaceable resources.
- Infrastructure is primarily created and configured manually.
- Infrastructure as Code is absent or used only for a small portion of the environment.
- Creating a new environment requires tickets and manual coordination between several infrastructure teams.
- Capacity is permanently provisioned for peak demand.
- Scaling means manually increasing VM size or adding additional servers.
- Development and test environments run continuously even when unused.
- Engineers routinely connect to servers to modify their configuration.
- Production servers gradually become unique systems that nobody wants to replace.
- Application deployment depends on manually prepared infrastructure.
- Network design attempts to reproduce the on-premises network as closely as possible.
- Existing organizational silos—network, storage, compute, security, operations—are reproduced in the cloud.
- Cloud costs are treated primarily as an infrastructure bill rather than something engineering teams can actively optimize.
- Resource ownership and cost allocation are unclear.
- Cloud services are selected mainly according to which traditional infrastructure component they resemble.
- New cloud capabilities are rejected because "that is not how we do it in the datacenter."
- Cloud adoption is considered complete once workloads have been migrated.
It is important to distinguish this antipattern from a migration strategy. Rehosting an application with minimal changes can be entirely rational. An organization may need to leave a datacenter before a contract expires, complete an acquisition, address hardware obsolescence, reduce migration risk, or move hundreds of applications within a limited timeframe. AWS itself recognizes rehosting as one of the available migration strategies.
The antipattern begins when "Move first, optimize later" quietly becomes "Move first, operate this way forever." Rehosting can be the first stage of a cloud journey. It should not automatically become its final architecture.
Negative effects on the organization
The most obvious problem is that the organization pays for cloud capabilities while using only a fraction of them. Its economic and operational advantages depend heavily on characteristics such as programmable infrastructure, elasticity, automation, managed services, consumption-based pricing, rapid provisioning, and the ability to create and destroy resources dynamically. If an organization provisions static virtual machines, operates them manually, maintains permanent excess capacity, and uses traditional ticket-based processes, many of those advantages disappear.
Traditional infrastructure encourages excess capacity because acquiring new hardware takes time. Cloud economics are different. Resources can often be provisioned rapidly and are generally charged according to consumption. Yet organizations frequently migrate systems sized according to datacenter assumptions and then run them continuously. A server that historically needed substantial spare capacity may become an equally oversized cloud instance running 24 hours a day. Development environments remain active overnight. Test systems run throughout weekends. Storage accumulates indefinitely.
In a traditional datacenter, provisioning infrastructure often involves physical actions. In cloud environments, infrastructure is exposed through APIs. This fundamentally changes what is possible. Networks, compute resources, IAM configurations, databases, policies, load balancers, and entire application environments can be described as code, versioned, reviewed, tested, and repeatedly deployed.
Manual configuration creates environments that are difficult to reproduce. Documentation diverges from reality. Changes become harder to review. Knowledge remains concentrated in the people who originally created the environment. The cloud becomes programmable infrastructure operated through human memory.
The Datacenter in the Sky often preserves another traditional habit: servers become individually important. They acquire names. Administrators modify them manually. Small configuration differences accumulate over time. Eventually engineers become reluctant to replace them because nobody is completely certain that a replacement will behave identically.
Cloud automation allows a different model. Where practical, infrastructure should be reproducible from known definitions. A failed or obsolete resource can then be replaced rather than carefully repaired.
This does not mean every workload must be ephemeral or stateless. It means avoiding unnecessary uniqueness. If a server can be recreated automatically, losing that particular server becomes far less significant.
Technology is only part of the problem. Organizations frequently migrate their existing structure together with their workloads. The networking team controls networks. The server team controls compute. The database team controls databases. The security team controls security configurations. Cloud platforms blur many of those boundaries. A single application deployment may define compute, networking, databases, IAM permissions, monitoring, and security configuration together as code. If every component still requires a separate organizational queue, technical automation alone cannot provide rapid delivery. The cloud environment may be capable of provisioning infrastructure in minutes while the organization requires weeks to authorize it.
This is why Datacenter in the Sky is fundamentally a management antipattern, not merely a technical architecture problem. An engineer can introduce Terraform. A platform team can create CI/CD pipelines. These changes require leadership support. Without it, technical teams are often forced to place cloud technology underneath the existing organization rather than redesigning the organization to take advantage of the technology.
The Healthy Pattern: Cloud as an Operating Model
The healthy alternative is to treat cloud adoption as an operating-model transformation supported by technology, rather than simply a change in infrastructure location. This does not require replacing everything at once. Instead, the organization progressively removes datacenter assumptions where doing so creates meaningful value. Infrastructure becomes increasingly reproducible through code. Teams receive appropriate self-service capabilities within defined security and governance boundaries. Elasticity is used where workloads benefit from it. Non-production resources can be stopped or removed when they are not required. Managed services are evaluated when they reduce undifferentiated operational work. Cost becomes an engineering consideration rather than simply a finance problem. Governance moves from manual approval toward automated guardrails where practical.
The principle is:
Moving infrastructure to the cloud is a migration. Changing how the organization builds and operates technology is cloud adoption.
A successful cloud journey should therefore not be measured primarily by how many servers have left the datacenter. It should be measured by whether the organization has gained capabilities it did not have before: faster delivery, greater automation, appropriate elasticity, improved resilience, better cost visibility, safer self-service, and the ability to adapt technology more quickly to business needs.